
Churn Prediction Models: How Subscription Brands Spot Who Will Cancel
Churn prediction models for subscription brands: the signals that work, rules and RFM first, then ML, how to test a model and act on scores legally.

Article summary
TL;DR
A churn prediction model scores each subscriber on how likely they are to cancel within a set window, using signals like skipped orders, pauses, failed payments and support tickets. Subscription brands should start with rules or RFM scores, move to logistic regression or gradient boosting once they have the data, and test every model on a later period.
- Define churn before you model it: which event, which window, which subscribers. Keep cancellations and failed payments as separate labels.
- Skips, pauses, frequency changes, failed or expiring cards and support tickets are the signals a subscription brand already has.
- Rules and RFM scores come first. Klaviyo's own churn risk is based on the number and frequency of orders.
- Judge a model on precision, recall and lift in the riskiest group, tested on a later period, never on accuracy alone.
- A score only pays off through an action, and save offers must leave the cancel button in place.
 ChatGPT
 Claude
 Perplexity
 Grok
On this page
A churn prediction model tells you which subscribers are likely to cancel before they do. Most guides on the topic are written for B2B software teams with data scientists and account managers. This one is for subscription ecommerce brands: which signals you already have, when rules beat machine learning, how to test a model honestly, and what you're allowed to do with the score.
What is a churn prediction model?
A churn prediction model gives each active subscriber a score: the likelihood that they churn within a window you choose. It learns from past subscribers whose outcome you already know, the ones who cancelled and the ones who stayed, and looks for the patterns that came before each outcome.3Braze Docs, Predictive Churn (read October 14, 2026)
The output is a number per customer. Klaviyo exports churn risk as a value from 0 to 1 and describes it as "the probability of a customer churning", based on "their number and frequency of orders".1Klaviyo Help Center, Guide to Klaviyo's predictive analytics (read October 14, 2026) Braze assigns a "churn risk score between 0 and 100".3Braze Docs, Predictive Churn (read October 14, 2026) Whatever the scale, the score answers one question: who should we look at first?
- Churn score
- 0.62, top 10% of subscribers
- Last 3 orders
- Skipped, skipped, shipped
- Frequency
- Changed from 4 to 8 weeks
- Support
- One ticket: flavor complaint
- Payment
- Card valid past next renewal
Illustrative example. The score ranks this subscriber against the others; the signals explain it.
A model doesn't tell you why a customer will leave, and it doesn't keep anyone. It sorts customers. What you do with that order, and whether it pays, is a separate question we cover further down. If you only need to know how many subscribers you lost last month, that's churn rate calculation, not prediction.
Define churn before you predict it
Every model learns one definition of churn. If the definition is vague, the model learns noise. Three choices come first:
- The event. A cancellation, a renewal that failed and was never recovered, or a customer who stops ordering. In subscription ecommerce, pauses complicate this: a three-month pause is not a cancellation, but a pause that's extended twice may be one in all but name.
- The window. "Will cancel in the next 60 days" and "will cancel before the next renewal" are different models. Braze lets you define churn as an action a user does or stops doing, over a window of up to 60 days.4Braze Docs, Create a churn prediction (read October 14, 2026)
- The population. Active subscribers only, or also one-time buyers? First-cycle subscribers churn for different reasons than two-year subscribers, and often deserve their own model.
- Observation windowPast behavior the model reads: orders, skips, tickets, payments
- Scoring dateThe day the score is computed. Nothing after it may enter the features
- Prediction windowThe period in which churn is counted, e.g. the next 60 days
- OutcomeChurned or stayed, by your definition
History matters more than model choice at this stage. Pendo's guide for its churn model asks for historical data "two to three times the prediction window", and enough history to capture 200 churned and 500 renewed accounts.5Pendo Help Center, Build a churn model in Pendo Predict (read October 14, 2026) Those are B2B account numbers, but the logic holds: you need enough past churners to learn from.
Keep voluntary and involuntary churn apart
A customer who clicks cancel and a renewal declined for insufficient funds both end a subscription. They are not the same problem, and one label for both teaches the model a blurred target. Stripe stores the reason a customer gives when cancelling through its portal, which gives you a clean label for voluntary churn.13Stripe Docs, Add a cancellation page to the customer portal Failed renewals have a decline code instead. Label them separately, model them separately if you model both, and send them to different fixes. We cover the payment side in subscription payment failures.
Churn signals that work for consumer subscriptions
B2B churn guides talk about logins, seats and feature adoption. A brand selling coffee, skincare or supplements by subscription has different signals, and most of them already sit in the subscription app, the checkout and the helpdesk.
| Signal | What it often means | Type of churn | Where the data lives |
|---|---|---|---|
| Skipped orders, especially in a row | Too much product, or interest fading | Voluntary | Subscription app |
| Pause, then pause extended | A break turning into an exit | Voluntary | Subscription app |
| Frequency changed to less often | Product not used as fast as planned | Voluntary | Subscription app |
| Visits to the cancel page without cancelling | Already considering it | Voluntary | Portal or site analytics |
| Card expiring before the next renewal | A decline is coming | Involuntary | Payment processor, card vault |
| Earlier soft declines, even if recovered | Fragile payment method | Involuntary | Payment processor |
| Support tickets on delivery, quality or billing | A problem that may not get fixed | Voluntary | Helpdesk |
| Only orders with a discount | Price-sensitive, may leave when the discount ends | Voluntary | Orders, discount codes |
| Falling email or SMS engagement | Attention moving elsewhere | Voluntary | Email and SMS platform |
| Order recency and count | The basic RFM signal | Both | Orders |
| Refund requests or disputes | Dissatisfaction, sometimes a hidden cancellation | Voluntary | Payments, helpdesk |
Two rules make these signals useful. First, change over time beats a single value: "skipped 2 of the last 3 orders" says more than "skipped once ever". Second, every signal must be measured as of the scoring date, from data that existed then. That second rule is where most models break, as we'll see in the pitfalls.
Start simple: rules and RFM scores
Before any machine learning, a few rules written with your retention team will catch a large share of at-risk subscribers, and give you a baseline any model must beat.
RFM is the classic version. It scores customers on recency (days since the last order), frequency (how often they order) and monetary value (how much they spend). Klaviyo's RFM report ranks each customer's percentile on each measure, converts it into a score from 1 to 3, and assigns a group such as Champions, Loyal, Needs attention, At risk or Inactive. "At risk" is defined as "a customer that has not purchased recently and/or tend to spend less overall".2Klaviyo Help Center, Understanding scoring and customer groups in the RFM report (read October 14, 2026) Free orders, such as 100% discounted ones, are left out of the analysis.2Klaviyo Help Center, Understanding scoring and customer groups in the RFM report (read October 14, 2026)
RFM was built for repeat purchase. For subscriptions, add the events RFM can't see. A rule set might look like this:
- 2 skips in the last 3 cyclesThe customer is stockpiling or losing interestOffer a frequency change before the next skip
- Pause extended at least onceThe break is becoming an exitAsk what changed; offer a swap or a smaller size
- Card expires before next renewalAn involuntary churn is scheduledCard update request, not a retention offer
- Quality or delivery ticket still openA broken promise, not a price problemFix the issue first; no discount
- Ordered 6+ times, no skipsStable subscriberLeave alone; no offer needed
Rules have two strengths over models: anyone can read them, and they work from the first week. Their weakness is that they don't weigh signals against each other. A subscriber with one skip, one ticket and a discount habit may be riskier than one with two skips, and only a model can tell you that from your data.
Machine learning models, explained plainly
When you have enough history and enough past churners, a statistical model can weigh dozens of signals at once. Three families cover almost every subscription use case.
Logistic regression
Gives each signal a weight and adds them up into a probability. Easy to read: you can see that a skip raises the score more than a ticket. The usual first model, and the one to beat.
Gradient boosting
Builds many small decision trees, each one correcting the errors of the previous ones. Picks up interactions, such as skips mattering only for new subscribers. Harder to explain, often stronger on messy data.
Survival analysis
Predicts when a subscriber will leave, not only whether. Handles subscribers who haven't churned yet without treating them as loyal forever. Fits renewal-based businesses well.
Logistic regression
Logistic regression is the standard starting point because its output is a probability and each input has a visible weight. scikit-learn notes that logistic regression is "more likely to return well calibrated predictions by itself", meaning a score of 0.8 tends to match an 80% churn rate among similar customers, provided the model is well specified and tuned.10scikit-learn, Probability calibration That property matters when you use the score to decide how much an offer is worth.
Gradient boosting
Gradient boosting stacks hundreds of shallow decision trees. It captures patterns a linear model misses, like a discount habit that only matters after the third order. scikit-learn's histogram-based version can be "orders of magnitude faster" than the classic one on tens of thousands of samples or more, and has "built-in support for missing values", which helps when a subscriber has never opened a ticket or never received an SMS.11scikit-learn, Ensembles: histogram-based gradient boosting The trade-off: its scores are not as well calibrated as logistic regression's, so check calibration before you put a price on a score.10scikit-learn, Probability calibration
Survival analysis
Classification asks "will this subscriber churn in the next 60 days?" Survival analysis asks "how long until this subscriber churns?" It was built to measure lifespans, and the lifelines documentation uses users subscribing to a service as an example.12lifelines documentation, Introduction to survival analysis Its key idea is censoring: a subscriber who is still active hasn't churned yet, but may later. The same documentation warns that ignoring these customers makes you "severely underestimating the true average lifespan".12lifelines documentation, Introduction to survival analysis For brands with long-lived subscribers, survival curves by cohort are often more useful than a single churn score.
| Rules and RFM | Logistic regression | Gradient boosting | Survival analysis | |
|---|---|---|---|---|
| Question answered | Who matches a risk pattern? | Who is likely to churn in the window? | Who is likely to churn in the window? | When is each subscriber likely to churn? |
| Data needed | Orders and subscription events | Labeled history with enough churners | More labeled history | Start dates, end dates, still-active subscribers |
| Easy to explain | Very | YesOne weight per signal | Needs extra tools | Curves are easy, models less so |
| Typical use | First version, small brands | First model, baseline | When the baseline plateaus | Renewal planning, cohort comparison |
Practical rule
Keep the simplest model that beats your rules on a later period. A gradient boosting model that adds nothing over logistic regression on next quarter's data is complexity you'll have to maintain for nothing.
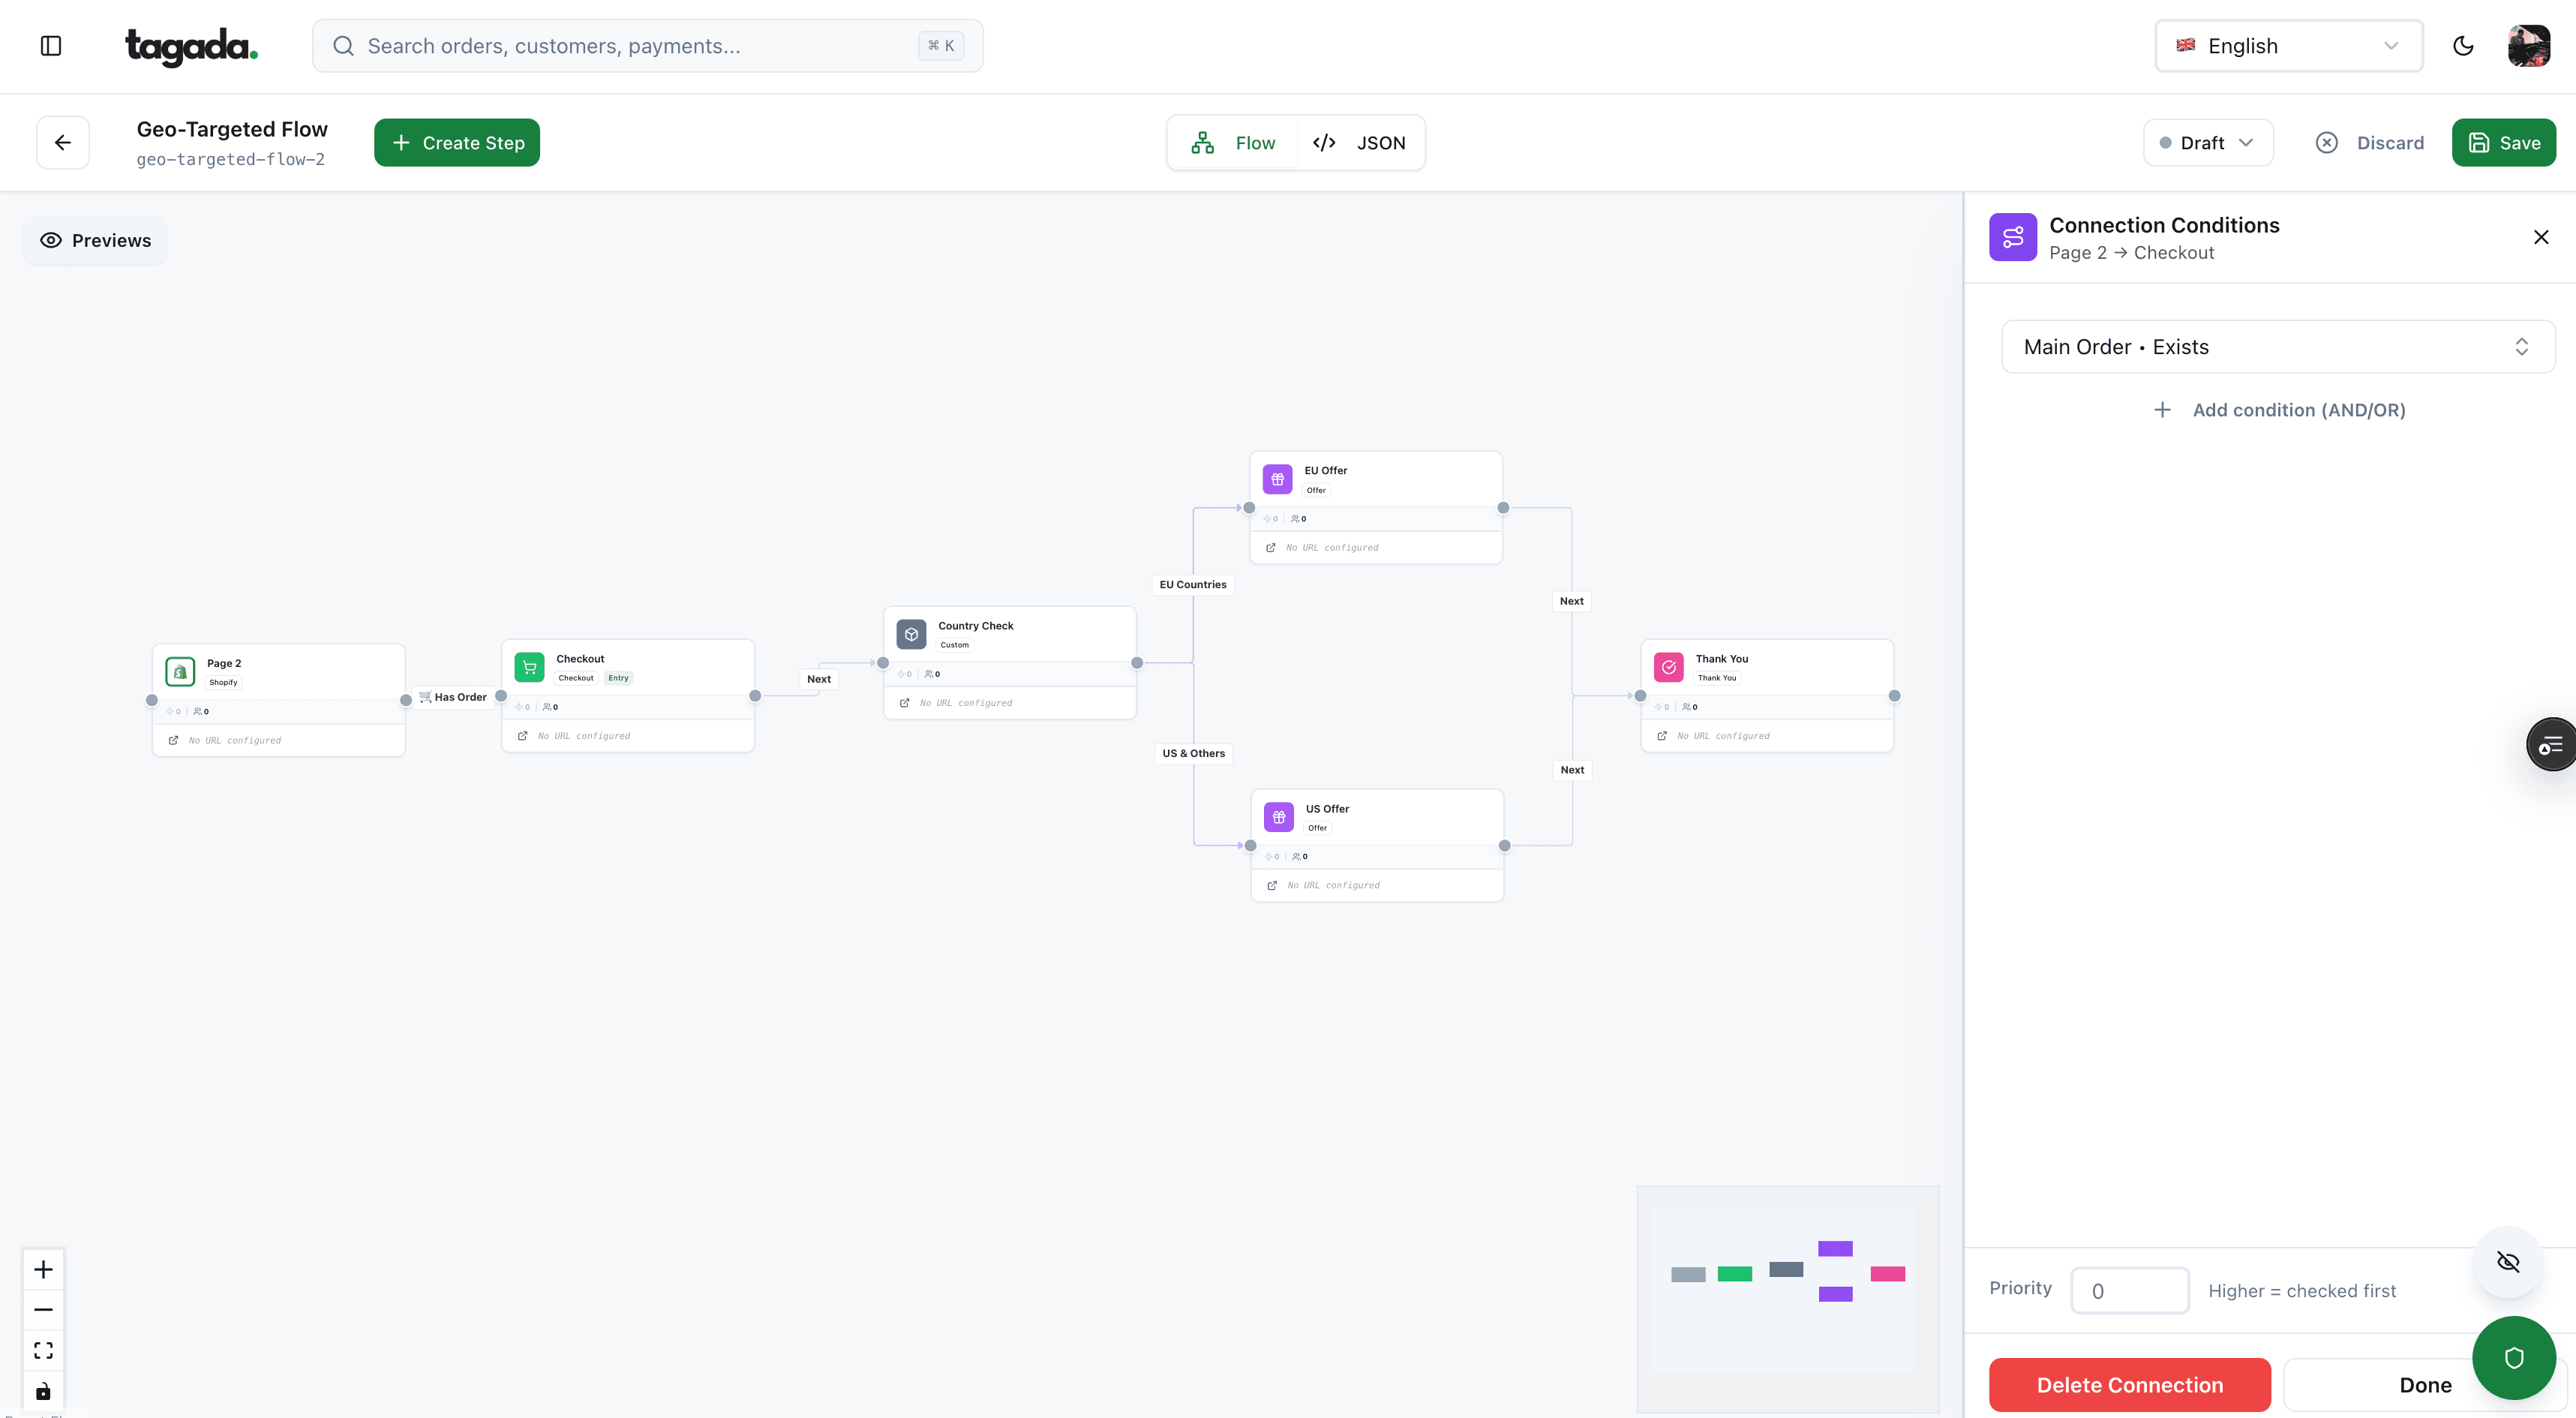
Inside Tagada
Build the funnel once, route every customer to the right offer
Checkout, upsells and subscriptions on one flow, with conditions per country, order or customer.
Build or use the score your tools already ship
You may not need to build anything. Several tools a subscription brand already uses ship a churn score, each with its own definition and data requirements.
| Tool | What the score is based on | Requirements stated in the docs | What you control |
|---|---|---|---|
| Klaviyo | Number and frequency of orders; probability from 0 to 1 | At least 500 customers with orders, 180 days of order history, orders in the last 30 days, some customers with 3+ orders | Segments and flows on the score |
| Braze | Your own definition: an action users do or stop doing | A minimum count of past churned and retained users, shown at setup | Churn definition, window up to 60 days, audience, refresh frequency |
| Subbly | A churn risk from 1% to 99% per active subscription | Built into the platform | Not documented on the page read |
| Pendo Predict | Product usage, for B2B accounts | 1 year of history or 200 churned and 500 renewed accounts, whichever is greater | Prediction window |
Sources: vendor pages, read October 14, 2026.1Klaviyo Help Center, Guide to Klaviyo's predictive analytics (read October 14, 2026)3Braze Docs, Predictive Churn (read October 14, 2026)4Braze Docs, Create a churn prediction (read October 14, 2026)5Pendo Help Center, Build a churn model in Pendo Predict (read October 14, 2026)6Subbly, Predictive Churn AI launch announcement (September 13, 2023, updated October 9, 2026) Braze retrains its model "every two weeks automatically" and charges extra for daily score updates.4Braze Docs, Create a churn prediction (read October 14, 2026) Klaviyo doesn't name its method; it says it "applies a combination of data science and machine learning techniques".1Klaviyo Help Center, Guide to Klaviyo's predictive analytics (read October 14, 2026)
Vendors also publish accuracy figures for their models. Subbly's 2023 launch reported accuracy "on training data", which says little about performance on new customers.6Subbly, Predictive Churn AI launch announcement (September 13, 2023, updated October 9, 2026) Treat any vendor accuracy number as measured their way, on their data, and test the score on your own subscribers before you trust it.
The limit of email-platform scores is what they see. Klaviyo's churn risk is built from orders.1Klaviyo Help Center, Guide to Klaviyo's predictive analytics (read October 14, 2026) It doesn't know about skips, pauses, tickets or an expiring card unless you send those events in. A score built on your subscription and payment data will usually see more.
How to evaluate a churn prediction model
A model that looks good in a notebook can be useless in production. Four checks keep you honest.
Don't trust accuracy
If 5% of your subscribers churn in a month, a model that predicts "nobody churns" is 95% accurate and catches no one. Use precision and recall instead. scikit-learn defines precision as "the ability of the classifier not to label as positive a sample that is negative", and recall as "the ability of the classifier to find all the positive samples".8scikit-learn, Metrics and scoring: precision, recall and ROC In churn terms: precision is the share of flagged subscribers who actually churn, recall is the share of churners you flagged.
Fig. 1Precision, recall and lift on one month of scores
| Churned | Stayed | Total | |
|---|---|---|---|
| Flagged (top 10%) | 300 | 700 | 1,000 |
| Not flagged | 200 | 8,800 | 9,000 |
| Total | 500 | 9,500 | 10,000 |
Illustrative numbers, not a benchmark.
In this example, precision is 300 ÷ 1,000 = 30%. Recall is 300 ÷ 500 = 60%. Accuracy is 91%, which says almost nothing.
Measure lift in the riskiest group
Lift compares the churn rate in your flagged group with the average. Here, 30% churn among flagged subscribers against 5% overall is a lift of 6: contacting the top 10% reaches six times more future churners than contacting 10% at random. Lift is the number that tells a retention team whether the list is worth working, and it maps directly to budget: you only pay for offers on the group you contact.
Test on a later period
Churn data has a time order. scikit-learn's documentation for TimeSeriesSplit warns that ordinary cross-validation is inappropriate for time-ordered data because it "would lead to training on future data and evaluating on past data".9scikit-learn, TimeSeriesSplit Train on, say, January to June, and test on July to September. If performance drops sharply on the later period, the model learned something that didn't last.
Check calibration if you price offers on the score
If you decide that a $10 offer is worth it above a 0.4 churn probability, 0.4 has to mean roughly 40%. scikit-learn describes a well calibrated classifier as one where, among customers scored near 0.8, "approximately 80% actually belong to the positive class".10scikit-learn, Probability calibration Plot predicted against actual churn by score band before you set thresholds.
How to act on churn scores
A score changes nothing until it triggers an action. The useful pattern combines the score, which says who, with the signals, which say what. A high score driven by skips calls for a frequency change; a high score driven by an expiring card calls for a card update.
- Score active subscribers on a fixed day, from data available that day only.
- Split by type. Payment risk goes to card update and dunning. Behavior risk goes to retention.
- Match the action to the main signal. Skips: frequency change or skip. Pause extended: swap or smaller size. Ticket: fix the problem. Price: a one-time offer, last.
- Hold out a control group. A random share of high-risk subscribers gets no action, so you can measure what the action changed.
- Compare churn after 2 or 3 renewals, not on the day, between contacted and holdout groups.
A weekly loop for a subscription brand. Keep the score refresh in step with the action: Braze makes the same point about update frequency.
The holdout is what separates prediction from retention. A model can predict churn perfectly and the offer can still change nothing, or only delay cancellation by one cycle. Without a group that got no offer, you can't tell the difference. For the tools that run these offers, see churn prevention software.
Save offers within the legal limits
A churn score can tell you who to show an offer to. It can never justify making cancellation harder for high-risk customers. The rules are the same whatever the score says; the full picture is in our guide to negative option billing.
What the rules allow
California allows a save offer during an online cancellation only if a "click to cancel" link or button is displayed at the same time, and the cancellation is processed promptly when clicked (§ 17602(e)).15California Business and Professions Code § 17602 ROSCA requires a simple mechanism to stop recurring charges.16Restore Online Shoppers' Confidence Act, 15 U.S.C. § 8403 Visa requires that cancellation be simple, and online when the order was taken online.17Visa Core Rules and Visa Product and Service Rules, April 18, 2026
Two more traps are specific to score-driven offers. A discount that ends is a promotional price: Visa requires a notice at least 7 days before the payment when a trial, introductory offer or promotion ends, with the amount, the date and a simple way to cancel.17Visa Core Rules and Visa Product and Service Rules, April 18, 2026 And a customer who restarts after cancelling is a new sign-up: ROSCA requires express informed consent before charging them again.16Restore Online Shoppers' Confidence Act, 15 U.S.C. § 8403
Pitfalls that make churn models lie
- Data leakageA feature contains information from after the scoring date
- Mixed churn typesFailed payments and cancellations in one label
- Rare churnersAccuracy looks high because almost no one churns
- Censored subscribers ignoredRecent subscribers treated as loyal
- DriftPricing, products or offers changed since training
Data leakage. scikit-learn defines it as information "that would not be available at prediction time" being used to build the model, which produces "overly optimistic performance estimates".7scikit-learn, Common pitfalls and recommended practices: data leakage In subscriptions, the classic leaks are a feature like "visited cancellation survey" or "subscription status" computed after the scoring date, or a "days since last order" measured at export time instead of at scoring time. The fix: build every feature as of the scoring date, and split your data before any preprocessing.7scikit-learn, Common pitfalls and recommended practices: data leakage
Involuntary churn mixed with voluntary. If failed renewals sit in the same label as cancellations, the model learns that "card expiring soon" predicts churn, and the retention team ends up sending discounts to customers who needed a card update. Stripe's Smart Retries, for example, don't retry hard declines like lost_card or stolen_card until a new payment method is added.14Stripe Docs, Automate payment retries (Smart Retries) No offer fixes that. Route payment risk to dunning and the renewal failure fixes, and keep the voluntary model for voluntary churn.
Rare churners. With a low churn rate, a model can look accurate while catching almost no churners. Compare models on precision, recall and lift, as above.
Censored subscribers. A subscriber who joined last month and is still active hasn't proven loyal. Dropping or mislabeling recent subscribers biases the model; survival analysis handles them by design.12lifelines documentation, Introduction to survival analysis
Your own offers change the data. Once you act on scores, the subscribers you saved look like non-churners in the next training set. Keep the holdout group running, and log every offer so the model can see it.
Drift. A new price, a new product or a new cancel flow changes behavior. Retrain on a schedule, and re-check performance on the latest period each time.
Where Tagada fits
How Tagada helps
Subscription and payment data in one place
Tagada runs subscriptions with trials, billing cycles, dunning and automatic recovery, alongside a checkout with one-click upsells. Payments route across Stripe, Adyen and Tagada's own processor, TagadaPay, with a cascade on decline, and the card vault moves customers between merchant accounts without collecting their cards again, so running subscriptions keep charging. That covers the involuntary side of churn before any model is needed. It runs standalone or with Shopify, WooCommerce or a headless store. Pricing is on the pricing page. Tagada follows Visa and Mastercard rules and the laws that apply to payments.
Whatever tool computes the score, the order stays the same: define churn and split it by cause, start with rules, test any model on a later period, act through a holdout, and never let a score stand between a customer and the cancel button.
Frequently asked questions
What is a churn prediction model?
Which model is best for churn prediction?
How much data do you need to build a churn prediction model?
What are the best predictors of churn for subscription ecommerce?
How do you evaluate a churn prediction model?
Can you predict involuntary churn?
Sources
Checked October 14, 2026- Klaviyo Help Center, Guide to Klaviyo's predictive analytics (read October 14, 2026)
- Klaviyo Help Center, Understanding scoring and customer groups in the RFM report (read October 14, 2026)
- Braze Docs, Predictive Churn (read October 14, 2026)
- Braze Docs, Create a churn prediction (read October 14, 2026)
- Pendo Help Center, Build a churn model in Pendo Predict (read October 14, 2026)
- Subbly, Predictive Churn AI launch announcement (September 13, 2023, updated October 9, 2026)
- scikit-learn, Common pitfalls and recommended practices: data leakage
- scikit-learn, Metrics and scoring: precision, recall and ROC
- scikit-learn, TimeSeriesSplit
- scikit-learn, Probability calibration
- scikit-learn, Ensembles: histogram-based gradient boosting
- lifelines documentation, Introduction to survival analysis
- Stripe Docs, Add a cancellation page to the customer portal
- Stripe Docs, Automate payment retries (Smart Retries)
- California Business and Professions Code § 17602
- Restore Online Shoppers' Confidence Act, 15 U.S.C. § 8403
- Visa Core Rules and Visa Product and Service Rules, April 18, 2026
Tagada
Running subscriptions? Keep renewals charging
Funnels, one-click upsells, subscription billing and payment routing, on one customer record.
- 01Create your free account
- 02Connect your store or build a checkout
- 03Launch funnels, upsells and subscriptions