
What Is A/B Testing? How to Run Ecommerce Tests You Can Trust
A/B testing for ecommerce: how a test works, a worked sample-size example, what to test in checkout and payments, the mistakes that fake wins, SEO rules.

Article summary
TL;DR
A/B testing shows two versions of a page, a checkout or a payment rule to randomly split groups of visitors at the same time, then compares one metric decided in advance. In ecommerce, that metric should be paid orders or revenue per visitor after refunds. Size the sample before launch, run full weeks, and don't stop early.
- One hypothesis, one change, one primary metric, all written before the test starts.
- Size the sample first. Detecting a move from 2.0% to 2.2% conversion takes about 80,700 sessions per version at 95% confidence and 80% power.
- Run full weeks and stop at the planned sample size. Stopping at the first significant result inflates false wins.
- Judge on revenue per visitor after refunds, with payment acceptance and disputes as guardrails. Clicks and add-to-carts aren't the result.
- For SEO, Google asks for no cloaking, rel=canonical on variant URLs, 302 redirects, and a test that ends when it's done.
 ChatGPT
 Claude
 Perplexity
 Grok
On this page
A/B testing is how an ecommerce brand stops arguing about changes and measures them instead. You split visitors at random between the current version and a changed one, and you let paid orders decide. This guide covers the method, a worked sample-size example, what to test in checkout and payments, and the mistakes that turn noise into fake wins. For supplement and skincare brands: A/B testing for supplement brands and A/B testing for skincare brands.
What is A/B testing?
An A/B test is a randomized controlled experiment. Version A is what you have today, the control. Version B changes one thing. Each visitor is assigned at random to one of the two, both run at the same time, and you compare a single metric chosen before the test starts.
Random assignment is what makes the comparison fair. Both groups see the same ads, the same weather, the same paydays and the same competitor sales. The only systematic difference is the change you made, so a difference in results larger than chance can be attributed to it.
Control (A)
The current page, checkout or payment rule, left untouched for the whole test.
Variant (B)
The same thing with one change: a shorter form, a different wallet order, a new route for one card segment.
Primary metric
The one number that decides the test, written down before launch. For a store: paid orders per session or revenue per visitor.
In ecommerce, "A/B testing" and "split testing" are used as synonyms. Strictly, a split URL test is a variant of A/B testing where version B lives at its own URL. The glossary entry for A/B testing gives the short definition; the rest of this guide is about running one that holds up.
How an ecommerce A/B test works, step by step
- Start from a leak. Funnel data shows where buyers drop: product page, cart, checkout, payment. A hypothesis tied to the step that leaks beats a list of ideas.
- Write the hypothesis. "Showing Apple Pay above the card form will raise paid orders per checkout session on mobile, because mobile buyers abandon at the card form." Change, expected effect, metric, reason.
- Pick one primary metric and a few guardrails. Primary: paid orders per session, or revenue per visitor for offer and pricing tests. Guardrails: payment acceptance rate, refunds, average order value.
- Size the sample. From your baseline rate and the smallest lift worth detecting, compute the sessions or visitors each version needs. Then convert that into full weeks.
- Assign by visitor, at random. A returning visitor must see the same version every time, or you're measuring confusion. Assign on a stable ID (a cookie or customer ID), and count results in the unit you assigned.
- Run full weeks, without peeking. Stop when the planned sample is reached, not on the first good day.
- Read the result, then the segments. Check the split was even, read the primary metric, check guardrails, then look at mobile and desktop separately before you ship.
Steps 1 to 4 happen before any visitor sees version B.
Steps 3 and 4 are where most store tests go wrong. A test judged on clicks, or stopped after four days, produces a winner that disappears once you ship it.
How big a sample do you need? A worked example
The sample depends on three inputs: your baseline rate, the smallest change you want to be able to detect, and how sure you want to be. The usual settings are 95% confidence (a 5% risk of calling a winner that isn't one) and 80% power (an 80% chance of detecting the lift if it's real).
Take a store converting 2.0% of sessions, testing a change that should lift conversion to 2.2%, a 10% relative lift. With the standard two-proportion test at 95% confidence and 80% power:
≈ 80,700
Sessions per version to detect 2.0% → 2.2%
≈ 161,400
Sessions in total, with a 50/50 split
≈ 21,100
Sessions per version to detect 2.0% → 2.4% instead
The same numbers appear in our guide to increasing your ecommerce conversion rate. The lesson is in the third figure: halving the lift you want to detect roughly quadruples the traffic you need.
Now turn sessions into calendar time. The count is sessions that reach the page you're testing, not sessions on the whole site.
| Daily sessions in the test | Days to detect 2.0% → 2.2% | Plan | Days to detect 2.0% → 2.4% | Plan |
|---|---|---|---|---|
| 5,000 | ≈ 32 | 5 weeks | ≈ 8.4 | 2 weeks |
| 10,000 | ≈ 16 | 3 weeks | ≈ 4.2 | 1 week |
| 20,000 | ≈ 8 | 2 weeks | ≈ 2.1 | 1 week |
| 50,000 | ≈ 3.2 | 1 week | under 1 | 1 week |
Every plan is rounded up to full weeks. Weekday and weekend buyers behave differently, and email sends and paydays land on specific days: a 10-day test counts three days twice.
How the number is computed
Per version: n = (1.96 + 0.84)² × [p₁(1 − p₁) + p₂(1 − p₂)] ÷ (p₂ − p₁)². With p₁ = 0.020 and p₂ = 0.022: 7.85 × 0.0412 ÷ 0.000004 ≈ 80,700. Any online sample-size calculator for two proportions gives the same result. For a checkout test, use the checkout's own completion rate as p₁, not the sitewide conversion rate.
If your store can't reach the sample in about four to six weeks, don't run a longer test. Test a bigger change, test where traffic is higher, or simply fix what's clearly broken (a hidden shipping cost, a broken mobile button) without testing it.
Why you can't stop a test early
Checking results every day and stopping the first time they look significant feels efficient. It isn't. The 95% confidence figure assumes the sample size was fixed in advance. Each extra look is another chance for random noise to cross the line.
Peeking inflates false wins
Evan Miller's classic example tests a change that does nothing and stops at the first significant reading: the false positive rate reaches 26.1%, more than five times the 5% you think you're taking. His fix is to fix the sample size in advance and not stop early, or to use a sequential method designed for early stopping.2Evan Miller, How Not To Run an A/B Test, April 18, 2010
Looking at a dashboard is fine. Acting on it before the planned sample is reached is the problem. Some testing tools use sequential statistics that allow early stopping by design; if yours does, follow its own stopping rule, not the standard p-value.
A/B vs multivariate vs split URL vs holdout tests
| Test type | What changes | Traffic needed | Use it for |
|---|---|---|---|
| A/B (or A/B/n) | One change, two or a few versions on the same URL | Baseline: one sample per version | Most store tests: copy, layout, wallet order, a form field |
| Multivariate | Several elements at once, every combination compared | One sample per combination: 3 elements × 2 options = 8 versions | Very high-traffic pages, to see how elements interact |
| Split URL | Version B lives at its own URL; visitors are redirected | Same as A/B | Full redesigns, a new checkout, a different platform |
| Holdout | A small share keeps the old experience for weeks or months | Small group, long duration | Measuring the total effect of everything you shipped, or a new routing setup |
| A/A | Two identical versions | Same as A/B | Checking that your tool splits traffic evenly and counts correctly |
Two practical rules follow. First, at 8 versions, a multivariate test comparing each combination with the control needs roughly eight times the traffic of a simple A/B test: most stores don't have it. Second, a holdout is worth keeping after you ship a change that touches payments. A small share left on the old route or old checkout shows whether the gain lasts, and catches drift when an issuer or processor changes its behavior.
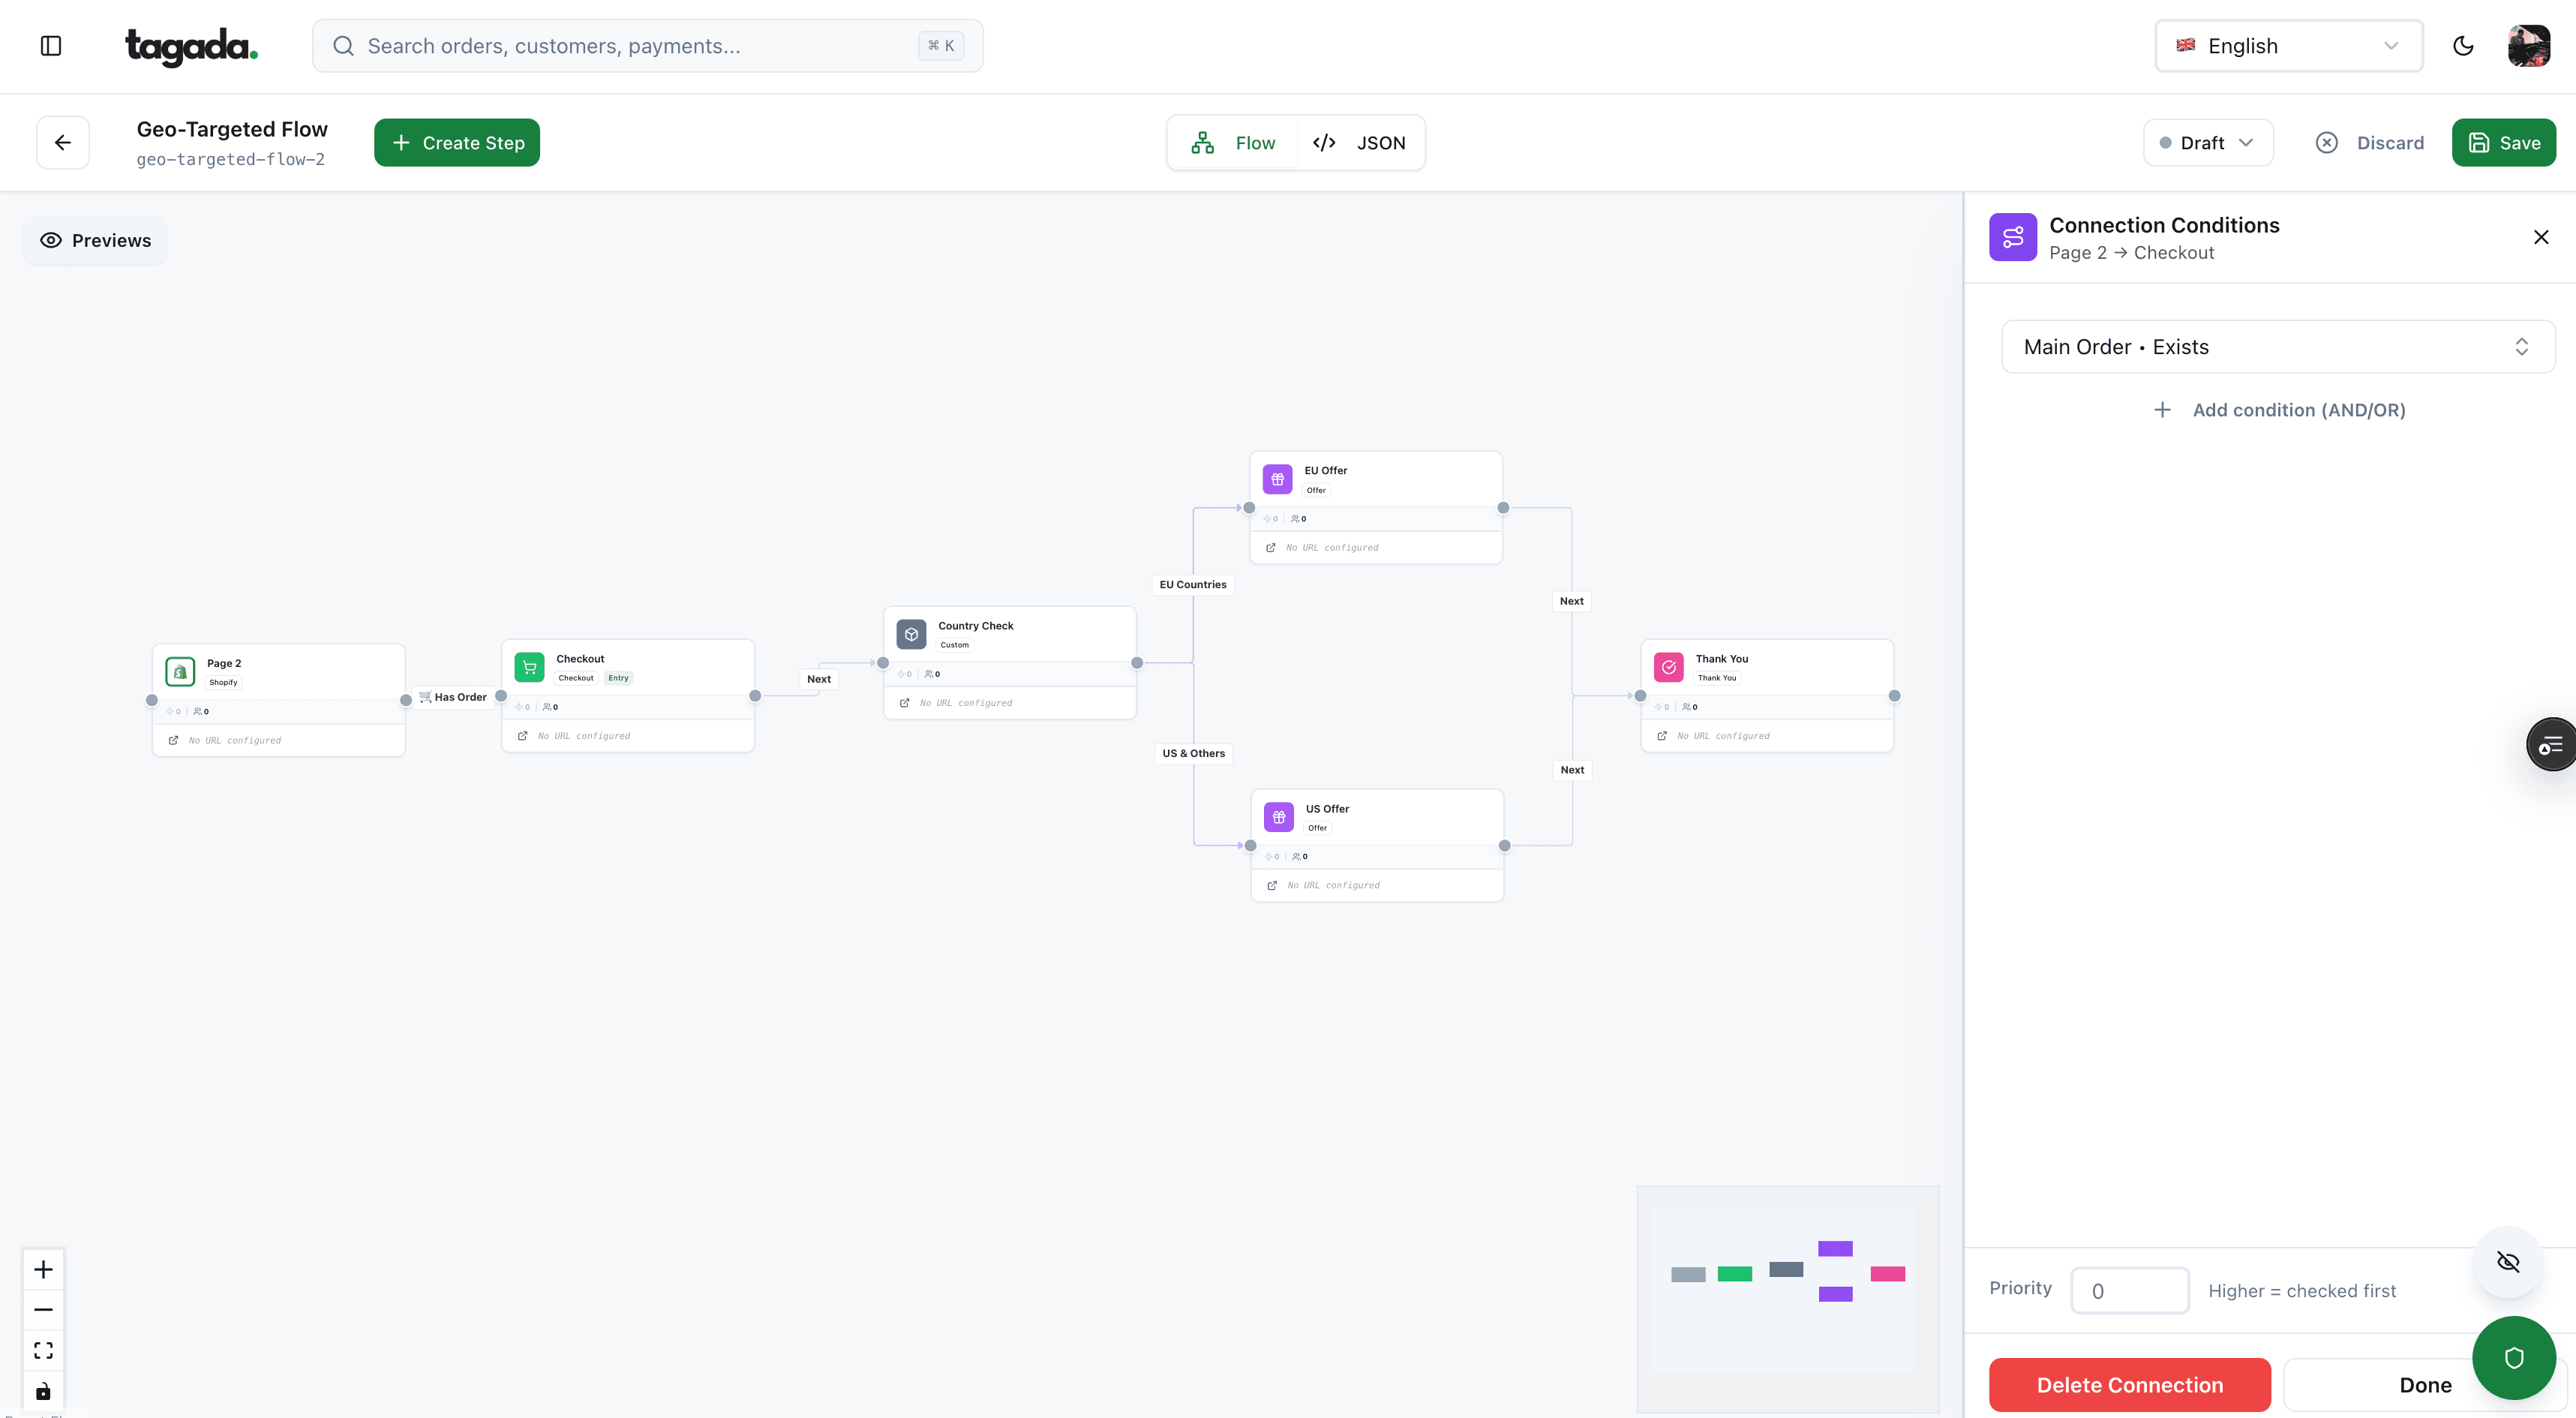
Inside Tagada
Build the funnel once, route every customer to the right offer
Checkout, upsells and subscriptions on one flow, with conditions per country, order or customer.
What to test in checkout and payments
Most testing advice stops at headlines and button colors. The steps closest to the money usually matter more, and they're where store tests are rarer. A few tests worth running, each with its own guardrail:
| Test | Primary metric | Guardrail | Read first |
|---|---|---|---|
| Wallet order: Apple Pay and Google Pay above the card form vs below | Paid orders per checkout session | Average order value, decline rate | Alternative payment methods |
| Guest checkout first vs account choice first | Paid orders per checkout session | Repeat purchase rate, fraud checks | Checkout as guest |
| One-page vs multi-step checkout | Completed orders ÷ checkouts started | Decline rate, 3D Secure completion | One-page checkout |
| Fewer form fields (single name field, address lookup) | Checkout completion | Delivery errors, fraud signals | Checkout page design |
| Order bump or post-purchase upsell vs none | Revenue per visitor | Refund rate, disputes | 1-click upsell |
| Payment route for one card segment | Authorization rate on unique payments | Disputes and fraud, weeks later | Dynamic payment routing |
Keep everything else identical. If version B changes the layout and also drops a field and adds a wallet, a win tells you nothing about which change worked. The ranked list of checkout fixes worth testing is in our ecommerce checkout optimization guide.
One trap is specific to checkout tests: a declined card looks like abandonment in most analytics tools. A layout that sends more buyers to a payment step that declines them shows "more abandonment" for a reason that has nothing to do with the layout. Join payment outcomes to the test before you read it.
How to A/B test payment routing
A routing test compares authorization rates between two routes on comparable traffic. Comparable is the hard part: if the new route gets mostly domestic debit cards and the old one keeps foreign credit cards, the difference is the card mix, not the route.
Fig. 1A fair routing test
Control: current route
- SegmentFor example: UK cards, first payments
- splitsRandom 50%Assigned per order, before the attempt
- routes toProcessor ACurrent setup, unchanged
Authorization rate on unique payments
Variant: new route
- SegmentSame segment, same days
- splitsRandom 50%Assigned per order, before the attempt
- routes toProcessor BNew route under test
Same metric, same period, same products
split by order, at random, inside one segment
- Count unique payments, not attempts. A card that fails twice and passes on the third try is one payment. Stripe suggests using card fingerprints instead of charge IDs to exclude repeat attempts.4Stripe Docs, Card declines
- Size it like any test. Authorization rates are high, so the sample is smaller than for conversion. Illustration: moving from 85% to 86% takes about 19,500 unique payments per route at 95% confidence and 80% power; from 85% to 87%, about 4,700.
- Never change the request to get a different answer. Visa's rules prohibit manipulating authorization data (acquirer, country, MCC, POS codes, ECI) when a declined transaction is resubmitted.5Visa Core Rules and Visa Product and Service Rules, April 18, 2026 Test routes on first attempts; test retries as their own experiment, within card network retry limits.
- Wait for disputes. A route that approves more fraud isn't better. Read the dispute and fraud rate per route a few weeks after the test.
The metric definitions are in payment acceptance rate, and the rules for routes and cascades in dynamic payment routing.
Metrics that matter: revenue per visitor after refunds
Conversion rate counts orders. It doesn't count what an order is worth, or whether the money stays. A discount, a pushier upsell or a free trial can raise conversion and still lose money. The metric that catches this is revenue per visitor, net of refunds.
An illustration with 40,000 sessions per version. Version B adds a 15% first-order discount banner:
| Version A (control) | Version B (15% off banner) | |
|---|---|---|
| Conversion rate | 2.0% (800 orders) | 2.3% (920 orders) |
| Average order value | $60 | $51 |
| Gross revenue | $48,000 | $46,920 |
| Refunds | 5% ($2,400) | 6% ($2,815) |
| Net revenue per visitor | $1.14 | $1.10 |
Verdict
B wins on conversion by 15% and loses on net revenue per visitor. Judge a store test on paid revenue per visitor after refunds, and treat clicks, add-to-carts and checkout starts as diagnostics, not results.
Two notes. Revenue per visitor varies far more from one visitor to the next than a yes-or-no conversion, so it needs a larger sample to reach significance; size the test on it if it's your primary metric. And refunds and disputes arrive late: for offer and upsell tests, read the net figure again after your refund window has passed.
Common A/B testing mistakes
- Planned 50/50, got 50,000 vs 48,800 visitorsSample ratio mismatch: a gap that size on that volume is far beyond chance (chi-square p < 0.001). Something drops users from one version: a redirect, a slow script, a bot filterDon't read the result. Find the cause, fix it, restart the test
- B wins big in week 1, then fadesNovelty effect: returning visitors react to anything new, then get used to itRead the result week by week and for new visitors alone before shipping
- The test ran over Black Friday or a big email launchPromotion buyers behave differently; the result may not hold the rest of the yearAvoid launching or stopping tests around promotions, or re-test in a normal period
- One of 12 metrics or segments is significantMultiple comparisons: at 5% each, five independent comparisons give about a 23% chance of at least one false winDecide on the primary metric only. Treat segment wins as new hypotheses, or tighten the threshold
- B looked significant on day 4 and you stoppedPeeking: the false positive rate is no longer 5%Stop only at the planned sample, in full weeks
- B changes copy, layout and price togetherA win can't be attributed to anythingOne change per test, or a multivariate design with the traffic for it
The sample ratio mismatch deserves its own note. Microsoft's experimentation team compares it to a fever: a symptom for a variety of data quality issues, and a reason not to trust the result until the cause is found.3Fabijan et al., Diagnosing Sample Ratio Mismatch in Online Controlled Experiments, KDD 2019 (Microsoft Research) Run a quick check on every test: compare the visitors in each version with the split you configured.
How to A/B test without hurting SEO
Google publishes its own guidance for site testing.1Google Search Central, Minimize A/B testing impact in Google Search, updated December 10, 2025 It boils down to four rules:
No cloaking
Don't show Googlebot one version and humans another, whether by server logic, robots.txt or any other method. Googlebot generally doesn't keep cookies, so it sees what cookieless visitors see.
rel=canonical on variants
In a split URL test, put rel=canonical on every alternate URL pointing to the original. Google recommends this over a noindex tag.
302, not 301
Redirect visitors from the original URL to a variant with a temporary 302 redirect (or a JavaScript redirect), never a permanent 301.
End the test
Run it only as long as necessary, then remove every element of the test. A test left running for a long time can be read as an attempt to deceive.
Small changes, such as the size, color, or placement of a button or image, or the text of your "call to action" ("Add to cart" vs. "Buy now!"), can have a surprising impact on users' interactions with your page, but often have little or no impact on that page's search result snippet or ranking.
Checkout and payment tests rarely touch indexed pages at all: checkout pages are usually kept out of search. The rules matter most for product, category and landing page tests.
Choosing a tool for checkout and payment tests
Most testing tools run a script in the browser that rewrites the page after it loads. That works for product pages and landing pages. It stops working once the test touches the checkout itself, a payment method's position inside a payment form, or which processor receives an order. Three questions sort the options:
- Where does the split happen? In the browser, on your server, or inside the checkout. Payment and routing tests need a server-side or checkout-level split.
- What can the result join to? A tool that only sees page events can't tell you whether the order was approved, refunded or disputed.
- Who assigns the visitor? The same visitor must stay in the same version across devices and sessions where possible, and the assignment must be logged for the sample ratio check.
Our A/B testing tools guide compares the main platforms. For tracking that survives ad blockers, see server-side tracking.
Where Tagada fits
How Tagada helps
A/B tests inside the checkout, routing behind it
Tagada's checkout comes with one-click upsells, order bumps, A/B tests, Apple Pay and Google Pay. Behind the payment step, it routes across TagadaPay and processors such as Stripe, NMI and Airwallex, with one logic and a cascade to another processor when one is down or times out, so checkout changes and payment outcomes live in the same system. Pricing is on the pricing page. Tagada follows Visa and Mastercard rules and the laws that apply to payments.
Whatever tool you use, the method is the same: a hypothesis tied to a leak, a sample sized before launch, full weeks, and a decision on revenue that stays in the bank.
Frequently asked questions
What is A/B testing in ecommerce?
How long should an A/B test run?
How much traffic do you need to A/B test?
What's the difference between A/B testing and multivariate testing?
Does A/B testing hurt SEO?
Which checkout providers let you A/B test payment flows?
Sources
Checked October 14, 2026- Google Search Central, Minimize A/B testing impact in Google Search, updated December 10, 2025
- Evan Miller, How Not To Run an A/B Test, April 18, 2010
- Fabijan et al., Diagnosing Sample Ratio Mismatch in Online Controlled Experiments, KDD 2019 (Microsoft Research)
- Stripe Docs, Card declines
- Visa Core Rules and Visa Product and Service Rules, April 18, 2026
Tagada
Checkout, A/B tests and payment routing in one place
Funnels, one-click upsells, subscription billing and payment routing, on one customer record.
- 01Create your free account
- 02Connect your store or build a checkout
- 03Launch funnels, upsells and subscriptions